
Originally published on Hearso Writing on 2026-09-27. Hearso is the team trivia game I build and run; these posts are the engineering notes from building it.
5,297 timed joins: 4 slow, none broken. Our fix stops waiting at 10 s but never cancels, because cancelling locked players out of their seat 3 times in 3.
On 2026-09-26, one run of our browser tests failed with a guest stuck on the play page. They had pressed Join, and nothing happened.
My first instinct was to call it flaky and press re-run. (Every engineer has a re-run button in their soul.) I'm glad I didn't.
Hearso is standup trivia: a host opens a room, and teammates join with a short code. So the question was simple. Is joining a room broken, or only slow? And if it is slow, what should a player see while they wait?
I timed 5,297 joins with Playwright against our DEV database, added temporary timing to the join route, and then reproduced each failure on purpose before fixing it.
Short answer: slow, not broken. Four joins in 5,297 took over 5 seconds: 5.1 s, 11.5 s, 11.9 s, and one that got no answer in 60 s. Every join that answered said 200.
The fix for players is a 10-second limit that stops listening but never cancels the request. Cancelling it, we found, locked a player out of their own seat in 3 runs of 3.
I also got the retry logic wrong once. A review caught it before it shipped, and that part of the story is below too.
It builds on How an answer reaches every screen, which describes the room a join enters, and What we got wrong about checks that pass when nothing happened, whose rule, "a check has to state what it examined", shaped the new test helper.
Why a join can take eleven seconds on a healthy database
A join is about six database round trips in a row: read the room, look for an existing seat, write the seat, and so on. From my laptop to DEV, each took roughly 60 to 70 ms. Add them up and a join takes well under a second.
The lobby moves to the room only after the join's POST answers. Our test pressed Join and asserted the room's URL with Playwright's default 5-second timeout. So 5 s was the whole budget for six sequential round trips.
That works until one round trip does not come back quickly.
What 5,297 timed joins showed
A temporary test pressed Join in a loop across six to seven parallel workers, between 21:58Z and 22:32Z. For each press it logged the status and the time to the join's answer. I ran it against a local production build (next start) talking to our DEV Supabase database.
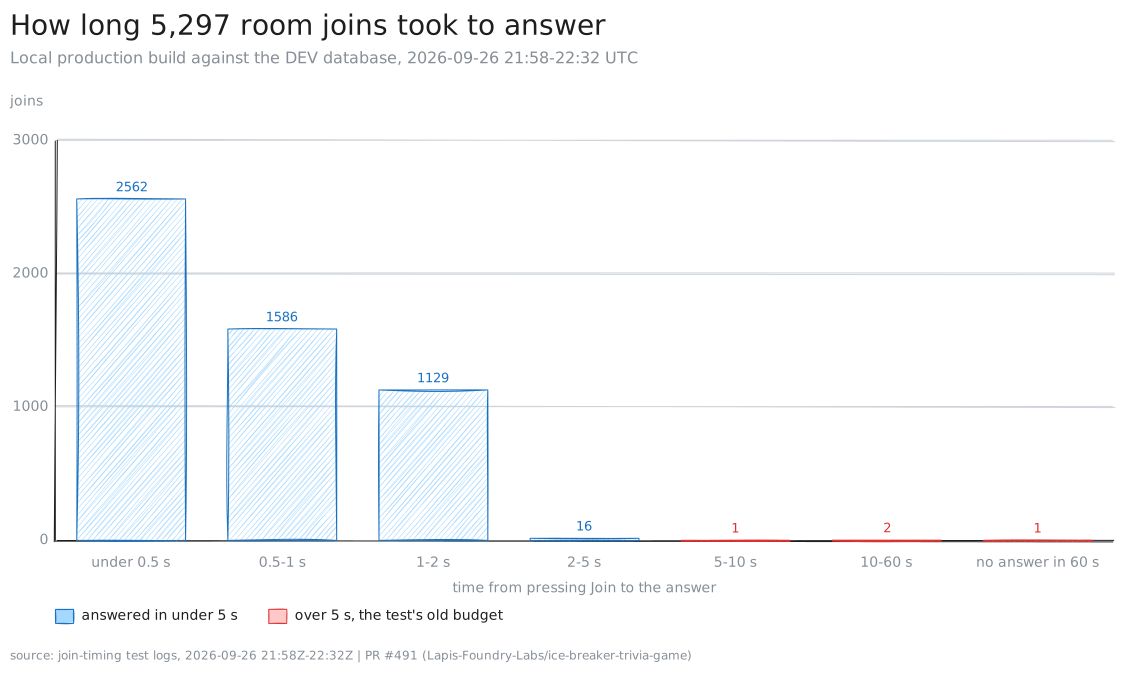
Figure 1. Every timed join on 2026-09-26, 21:58Z-22:32Z, n = 5,297, both shells together. The four red bars are the only joins over 5 s.
| Joins timed | Answered 200 | Over 5 s | The slow ones |
|---|---|---|---|
| 5,297 | 5,296 | 4 | 5.1 s, 11.5 s, 11.9 s, and one with no answer in 60 s |
Figure 1 shows the shape: a big healthy lump, and four outliers. The per-run numbers are in How we measured.
Here's a real example. The three slow classic joins took 5,093 ms, 11,870 ms and 11,453 ms.
They came from three different workers (0, 4 and 1), sent within 26 seconds of each other, at 22:04:20.8Z, 22:04:34.1Z and 22:04:46.8Z. In each one, the time to the first byte of the answer was about 99% of the total. The browser was not slow. The server was waiting.
Where the time went
The temporary timing in the join route answered that. Every slow join spent its time in one read:
- at 22:18:37Z, a single room read took 11,446 ms;
- at 22:20:52Z, three separate joins each stalled about 61 s (61,460, 61,433 and 61,416 ms), each in one read, in the same second. These are server-log events from the platform run, which also carried 12 gameplay tests; only one of the 5,297 timed joins went unanswered in 60 s, so at most one of the three is in the timed sample, and the logs don't say which;
- around 22:21Z, in the same episode, three room creations failed to reach their room within 20 s.
So the slow joins came in short episodes that crossed workers, not as a steady tail.
The shapes are suspicious: about 10 s plus 1 s, and about 60 s plus 1 s. Our database client, postgrest-js 2.109.0, retries a GET after a network error and waits 1 s before the first retry. A read whose connection failed at about 10 s, waited 1 s, then succeeded quickly would produce exactly these totals.
That is likely, not proven. A retried request carries an X-Retry-Count header, and I did not record it.
The test's 5-second budget was the bug
Before changing the test, I checked that this really was the failure. I held the join for 6 s with route interception. The old three lines of test failed 5 runs of 5, stuck on /games/trivia/play with "Timeout: 5000ms": the original symptom, on demand.
The new helper, joinRoomByCode, waits on the join's own POST with a 20 s budget. It passed 5 of 5. When it fails, it says which of three things happened:
- no answer within 20 s, and the page said nothing;
- a refusal, with its status and body;
- an answer of 200, and the page still did not move to the room.
It also presses again when the page says the join is taking longer, as a player would, up to three presses. A failure that names its cause is one you can act on. The old one said only that the URL was still wrong after 5,000 ms.
What should a player see after ten seconds?
The test was fixed. The player's problem was not. A join could sit on "Joining..." for up to about a minute, because nothing put a deadline on the request.
At 22:35Z I wrote down three options: leave it, add a client deadline with a Try again button, or add a server-side time limit on these reads. I recommended the client deadline, and wrote why it was safe: "a retry is safe, since a returning player's seat is restored."
At about 22:45Z we chose it, with a 10-second limit and a manual retry. After 10 s the page says "This is taking longer than usual. Try again." and the button works again. Nothing retries by itself. The classic runs' p99 was under 0.7 s, so an ordinary join never meets the limit; only the stalls do.
Every join path now goes through one helper, lib/room-join-request.ts: the lobby's code box, the Live tab's code box, the classic /rooms directory, and the room page's own join for shared links.
The prediction from 22:35Z, that a retry is safe, was half right. It missed how the seat is restored.
Why we never cancel a slow join
Think of a coat check. You hand over your coat, and the attendant hands back a ticket. If you walk away before the ticket reaches you, your coat is still on the rail, but you can no longer prove it is yours.
A seat in a Hearso room works the same way. It belongs to a browser through an httpOnly cookie, a cookie the page's own code cannot read or set, and only the join's answer sets it. A stalled join usually still finishes on the server: the slow read comes back, and the seat is written. If the page aborts the request, the browser throws that answer away, cookie included.
We did not assume this. A temporary test let the server finish a join, then removed the cookie before the page saw the answer, which is what an abort does. Then it pressed Join again. In 3 runs of 3, the first join got 200 on the server, the retry got 401 "Rejoin this room from the browser you joined with", and the host's roster read "2 joined".
The player held a seat and was locked out of it.
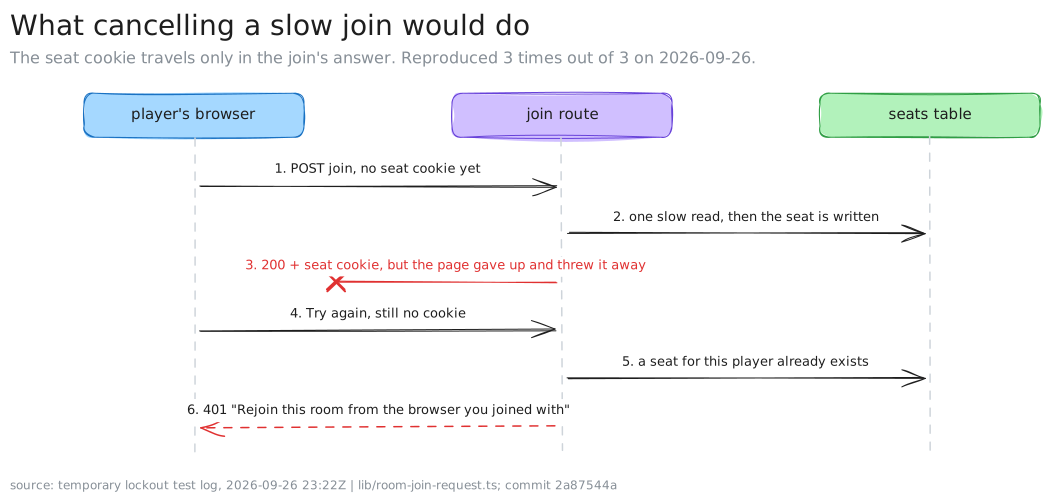
Figure 2. What cancelling would do, reproduced 3 times out of 3 on 2026-09-26 at 23:22Z with a temporary browser test against DEV.
A deadline is there for the person waiting. The request does not need one, and here it has a reason to finish. So after 10 s the page stops listening, not the request. The deadline is a race, not a cancellation:
const deadline = new Promise<JoinOutcome>((resolve) => {
  timer = setTimeout(() => resolve({ kind: "slow" }), deadlineMs);
});
const outcome = Promise.race([send(code, identity), deadline]);
There is no AbortController in that file, on purpose. When the late answer lands, the browser still stores the cookie, and the next press is recognised as the seat's owner. The late answer itself changes nothing on screen.
Can a retry seat someone twice?
A retry sounds like a way to create duplicates. It cannot here, and the reason is in the schema, not in the page: room_players has PRIMARY KEY (room_code, player_id).
The route writes a new seat with a plain INSERT, not an upsert. If two requests race, the key lets exactly one create the row and receive the cookie. The loser gets Postgres error 23505, which the route turns into the same 401.
Route tests pin both halves, for a guest and for a signed-in player: without the cookie a retry is refused, and with it the retry is admitted to the same row, never a second one.
I judged the 401 at the wrong moment
One case was left. A retry sent while the first join is still unanswered carries no cookie. If the first request has already written the seat, the route answers the retry 401.
That 401 does not mean "someone else holds this seat". It means "your own earlier attempt does". The page should say "still slow", and the next press gets in.
My first version decided this when the 401 arrived: is an earlier attempt still unanswered right now? An independent local review, before I opened the pull request, found the ordering that breaks it. The earlier answer can land first: its 200 and cookie at 11.0 s, then the retry's 401 at 11.2 s.
By then nothing is unanswered, so the 401 read as a refusal. On the room page, that meant a fatal "Rejoin" screen over a seat the browser now held.
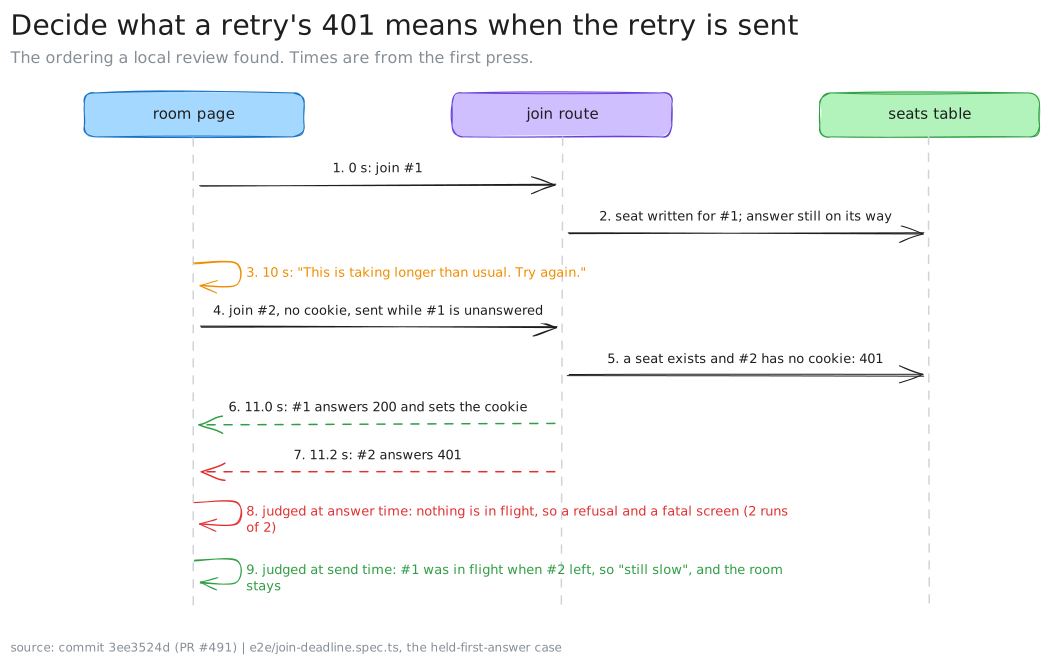
Figure 3. The two answers can cross. With the answer-time rule, a browser test rendered the fatal screen in 2 runs of 2; the send-time rule keeps the room.
What makes the 401 harmless is what was in flight when the retry left, so that is what the helper now records:
// Whether an earlier attempt for this room was still unanswered as this one left.
const earlierAtSend = count(code) > 0;
unanswered.set(code, count(code) + 1);
// ...later, when this request's answer arrives:
const earlierStillOut = earlierAtSend || count(code) > 1;
release(code);
if (response.ok) return { kind: "joined" };
if (response.status === 401 && earlierStillOut) return { kind: "slow" };
It stays bounded. A press sent with nothing earlier in flight still gets its 401 as the refusal it is. The browser test that reproduces the reviewer's order is now part of e2e/join-deadline.spec.ts.
The review found a bug older than the branch
The automated review on the pull request found one more issue, and it was real. On the room page, a join that failed with a 5xx or no connection was still marked settled. The next poll's 401 then read as "this browser never joined", and the page showed "This room does not exist (or has been cleaned up)." for good.
This bug predated the branch. A newcomer arriving from a shared link whose join failed was told the room did not exist.
Now only a successful join or a 4xx refusal settles the join. Anything else says "We could not reach the room just now. Try again." with the same button.
Room creation stays slow, on purpose
Room creation has the same exposure: three creations stalled past 20 s in the same episode. It does not get a Try again.
A retry there could open a second room, which is not the same kind of mistake as a slow join. The tests' createRoom now waits on the create's own answer and names its failures, but the page is unchanged.
One question decided both cases: what does a second attempt do if the first one had already succeeded? For a join, the primary key makes it harmless. For a creation, nothing does yet.
Predictions vs outcome
| Prediction | What happened | Right? |
|---|---|---|
| The failure means a broken join, or a flaky test | 4 of 5,297 joins were slow; every answer was 200. The test's 5 s budget was the fault | No |
| The stalls are postgrest-js retrying after a network error | The shapes fit (10 s + 1 s, 60 s + 1 s); the retry header was not recorded | Unknown |
| "A retry is safe, since a returning player's seat is restored" (22:35Z) | Only if the first request is not cancelled. With its answer dropped, the retry was locked out 3 of 3 | Half |
| A retry could seat a player twice | Impossible: the primary key lets exactly one INSERT win | No |
| A 401 can be judged when it arrives (my first version) | The answers can cross; the fatal screen appeared 2 of 2 | No |
Key takeaways
- Time the thing before you fix the test. "Flaky" was four slow joins in 5,297, none of them broken.
- Let a deadline stop waiting without cancelling. If the answer carries state, such as a cookie, a cancelled request throws that state away.
- Let the database make duplicates impossible. A primary key made "try again" safe, so the page did not have to.
- Judge an answer by what was true when the request left. When two answers can cross, the state at arrival time is a guess.
- Reproduce the failure first, then the fix. The old test failed 5 of 5 on a 6 s delay, the lockout 3 of 3, the answer-time rule 2 of 2.
What I'd do next
- Record the
X-Retry-Countheader from the first run. The postgrest-js explanation fits every shape I saw, and I still cannot say it is true. - Time production joins. Every number here is DEV, from one laptop.
- Consider the option we did not build: a server-side time limit on these reads.
- Give room creation its own answer to "what does the player see while it is slow", one that cannot create a second room.
How we measured
- Setup. A local production build (
next start) on my laptop, against the DEV Supabase database, 2026-09-26. A temporary Playwright test pressed Join in a loop across six to seven workers and wrote one line per join: status, time to answer, time to first byte. - Percentiles are nearest-rank, over each run's own answers.
- The platform run shared the machine with 12 gameplay tests, so its p50 is not comparable with the classic rows. Its one failure is the join that got no answer at all in 60 s.
- Server timing came from temporary logging in the join route, per database step.
- What we did not measure: production joins; the
X-Retry-Countheader on the stalled requests; anything but DEV from one laptop.
| Run (2026-09-26, UTC) | Shell | Joins | p50 | p99 | Slowest | Over 5 s |
|---|---|---|---|---|---|---|
| 21:58, calibration | classic | 60 | 437 ms | 620 ms | 3,741 ms | 0 |
| 21:59-22:02, with the full suite | classic | 240 | 374 ms | 661 ms | 864 ms | 0 |
| 22:02-22:05 | classic | 600 | 405 ms | 689 ms | 11,870 ms | 3 |
| 22:07-22:14, route timed step by step | classic | 2,000 | 395 ms | 677 ms | 1,649 ms | 0 |
| 22:15-22:32, beside 12 gameplay tests | platform | 2,397 | 978 ms | 1,856 ms | no answer in 60 s | 1 |
Evidence
All times UTC.
- The first failure and its cause: overnight handoff, 2026-09-26, entry 22:35Z; commit
6eb82928(the old test failed 5/5 on a 6 s delay, "Timeout: 5000ms"; the helper passed 5/5; "about six sequential database round trips"). - The 5,297 joins (Figure 1, the tables): six join-timing test logs, 2026-09-26 21:58Z-22:32Z, one line per join with its status, time to answer and time to first byte. Totals: 5,296 answered, all 200, plus one "Timeout 60000ms exceeded" with no answer. The handoff entry at 22:35Z records the same four slow joins (5.1, 11.9, 11.5 s and one with no answer). The raw logs were temporary files and are no longer kept; the numbers here were taken from them on 2026-09-26 and 2026-09-27.
- The three slow classic joins: 5,093 ms (first byte 5,038 ms), 11,870 ms (11,822 ms) and 11,453 ms (11,403 ms), sent at 22:04:20.8Z, 22:04:34.1Z and 22:04:46.8Z from workers 0, 4 and 1.
- The one slow read: server logs of the temporarily instrumented join route; room read 11,446 ms at 22:18:37Z; three joins at 22:20:52Z stalled 61,460 ms, 61,433 ms and 61,416 ms in one read each.
- Three stalled creations: platform run log, three failures to reach the room around 22:21Z; the helper of that time waited 15 s plus a default 5 s.
- postgrest-js retry:
@supabase/postgrest-js2.109.0,dist/index.mjs(retries GET, HEAD and OPTIONS after a network error; first delay 1 s; setsX-Retry-Count). Re-read on 2026-09-28. Not recorded on the stalled requests. - The options, the prediction and the 10 s choice: handoff entry 22:35Z (options a, b and c; "a retry is safe, since a returning player's seat is restored"; 10 s chosen about 22:45Z);
lib/room-join-request.ts(JOIN_ANSWER_DEADLINE_MS = 10_000, noAbortController). - The helper:
joinRoomByCodeine2e/support/gameplay.ts(commita426f7fe), which presses throughjoinRoomThroughup to three times. - The lockout, 3/3: temporary lockout test, 2026-09-26 23:22Z; commit
2a87544a. - No duplicate seat: base schema migration (
room_players_pkeyonroom_code, player_id);app/api/rooms/[code]/join/route.ts(INSERT,23505to 401); route tests in PR #491. - Send time, not answer time, 2/2: commit
3ee3524d; the browser test in commit4f206a84. - The older room-page bug: review thread on PR #491 (2026-09-27, about 01:10Z); fix in commit
529cc41a. - Merged: PR #491 into the beta.9 release branch, 2026-09-27T01:36:15Z.
No credential, token or player identity appears in this post or its figures. The room codes in the raw logs belong to test rooms and are not reproduced here.