
Originally published on Hearso Writing on 2026-09-18. Hearso is the team trivia game I build and run; these posts are the engineering notes from building it.
Our soak runner printed FAIL for numbers that were not in yet, so a healthy two-hour run was stopped at minute 38. The restart passed all 14 conditions.
At minute 30 of a two-hour soak, my runner posted a progress entry listing nine failed conditions. The service was healthy, and the run was stopped at minute 38 anyway.
The service was hearso-rt, the new Rust WebSocket game service behind Hearso's live trivia rooms. On 2026-09-18 a web-side agent and a service-side agent ran an overnight cutover moving rooms onto it behind a per-room switch, locally, with nothing deployed. They worked through one append-only file, the cutover log, and every number here comes from it.
The bug was mine. It was also the fourth start of that soak that ended without a verdict.
What I wanted to know was simple: can hearso-rt hold rooms open for two hours without losing a game, a connection or a database row?
We used a purpose-built soak runner driving ten rooms of bot players through Next.js and the socket, sampling Uptime Kuma and Postgres beside it.
Short answer: yes, for ten rooms on one laptop. The fifth start ran 120 minutes and passed all 14 conditions: 350 games, 553 reconnects, zero violations, snapshot p95 1 ms, and memory up 1.95% against a 10% limit.
Getting there cost three false starts on sizing and ordering, and one message my own tool wrote.
A soak test is a tap left running overnight
Think of a tap that doesn't drip. Turn it on for a second and it looks fine; leave it running overnight and you find out whether the washer holds.
A soak test runs a normal workload at a normal rate for a long, fixed time, watching for faults that only show with age: memory that never comes back, handles that pile up, a queue falling behind.
Ours was two hours of bot games in ten rooms, with one number aimed squarely at age: hearso-rt's resident memory had to grow less than 10% between minute 15 and minute 120. Minute 15 is the baseline because a process that has just started is still filling caches.
hearso-rt holds a socket per player for a whole game, and every live room is state it owns until something cleans it up. Ten seconds of traffic can't tell that service apart from one that never tidies up.
Seven conditions became fourteen numbers
Section 12 of the plan set the bar:
- zero invariant violations;
- zero
1011closes; - zero 5xx from Next.js;
- no outbox row unprocessed for over 60 seconds;
- every Uptime Kuma monitor up throughout;
- memory growth under 10% from minute 15;
- p95 snapshot delivery under 50 ms.
Two need a word. A 1011 is the close code a WebSocket server sends on an internal error it can't recover from. An outbox row is the record we write in the same transaction as a finished game; one unprocessed after 60 seconds means delivery is falling behind while the games look fine.
The runner turns those seven into fourteen numbers. The other seven are mine: one fault the plan didn't name, two asking whether the workload ran at all, one enforcing the rule that a runtime commit voids the soak, and three asking whether the run was measured.
That last group exists because of a trap we've hit before. A maximum over an empty set of samples is zero, and zero violations is what a passing soak looks like.
So the runner never reports a number it didn't take. It reports -1, a sentinel: for a counter that can never be negative, such as invariant violations, a value outside the real range that stands for "no value". (Memory growth can be negative, so it isn't read that way.) Ours read -1 for invariant violations at minute 30 and 0 at minute 120. At the end, -1 fails, because a condition nobody measured isn't one that passed.
That rule is right. It's also what stopped a healthy run 38 minutes in.
The runner refuses to start until three gates hold
That story comes further down. First, the part of the runner that did what it was built for.
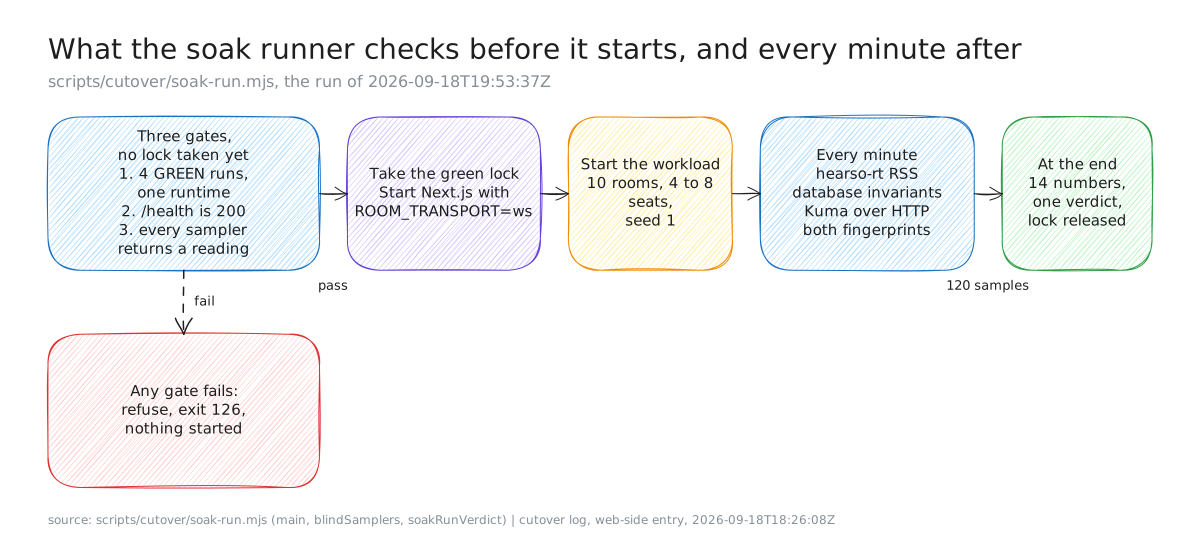
Figure 1. The order the runner enforces, from scripts/cutover/soak-run.mjs.
The runner refuses to start unless three things hold, checked before it locks or launches anything:
- Four GREEN verification runs must end the results list on identical runtime fingerprints. Ours were 18:11:12Z, 18:25:16Z, 18:39:13Z and 19:12:11Z, nine checks passing each time on one Rust commit.
/healthmust answer 200.- Every sampler must return a reading at minute 0.
I wouldn't give up that third gate. Earlier that evening, Kuma credentials that never reached a checker cost us a red run and a quarter of an hour; asked at minute 0, the same fault costs a minute. Kuma listing zero monitors isn't a reading either: zero is what a login page parses to.
Only then does the runner take the lock that owns port 3100, start Next.js with the WebSocket transport switched on, and start the bots.
The workload: ten rooms of seeded chaos
The bots play ten rooms at once, four to eight seats each, joining through the same Next.js ticket routes a browser uses. A room plays three games and is abandoned, and a new one opens in its slot: 121 rooms in all by minute 118.
The chaos is seeded, so a bad night can be replayed. On each snapshot a bot receives during a game, it reconnects with probability 0.003 and leaves for good with 0.001, and it only leaves while more than three seats remain. The host can be the one who leaves, which is the only thing that exercises host succession.
One seat abstains from every rematch vote, so the room must reach a majority carrying a non-voter. Snapshot delivery is timed per frame: the service's own timestamp against the moment this process received it.
Three false starts, and a rehearsal that "failed"
None of that ran cleanly the first time, and most of what went wrong was outside the gates.
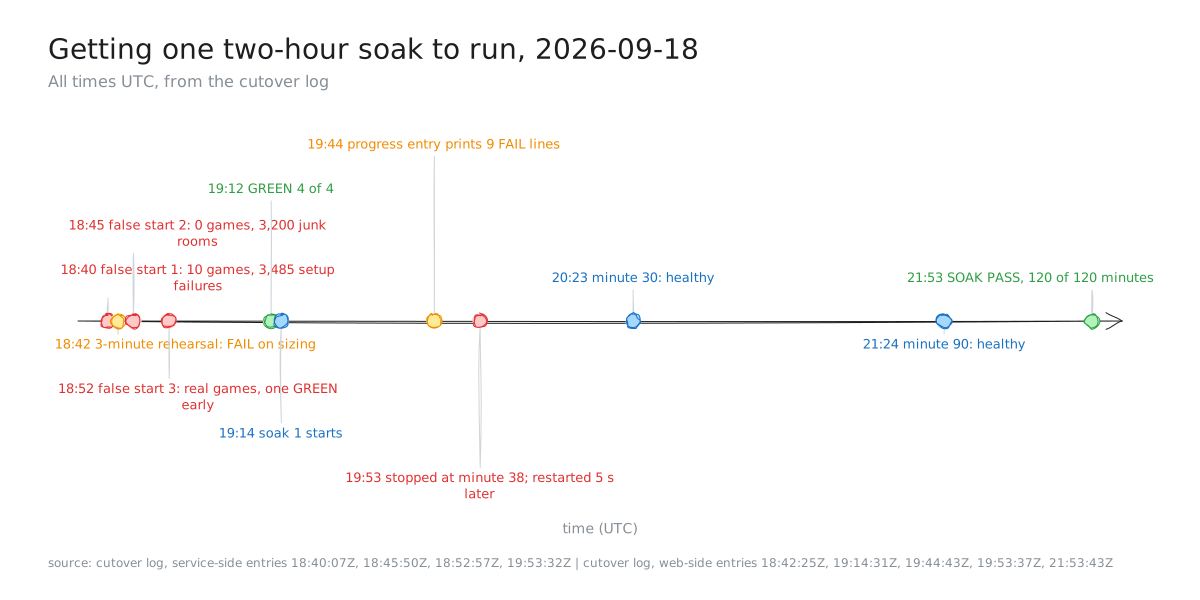
Figure 2. Seven moments on 2026-09-18 (UTC), from the cutover log. The four events of 18:40 to 18:57 are drawn as one; the text below lists each.
The soak script that arrived first couldn't fail. For two hours it ran two checkers every thirty minutes and slept. It started no room, no bot and no socket, and it ended every command in || true.
Sixteen lines, and a two-hour soak of an idle service passes by construction. It's the shape of a sweep job of ours that ran for a day and collected zero of twelve qualifying rooms (web PR #425).
Then three soaks were started before the fourth GREEN run existed. The first, at 18:40:07Z, borrowed a Next.js server my three-minute rehearsal was about to stop. It left 3,495 bot evidence files: 10 games played, 3,485 failed at setup.
The second, at 18:45:50Z, ran against a Next.js restarted with the WebSocket transport switched off, so every room was stamped poll and the ticket route answered 409.
No loop checked an exit code and none paused, so ten ran flat out. They left 2,856 artifacts, every one a setup failure, and wrote 3,200 rooms with 11,787 player rows in about 100 seconds, at a load average of 15. The third, at 18:52:57Z, was a real workload, but still one GREEN early.
My own rehearsal "failed" too: games_finished 0, workload_exit 1, rss_growth_percent 45.98. None of it was about the service. A game takes about 200 seconds and I'd sized the rehearsal at 180; and the memory baseline is an eighth of the run, so three minutes measures growth from minute 0.
What it did prove is the plumbing: nine samples at twenty seconds, every sampler reading every time, Kuma 7 of 7, zero violations, zero 1011, zero 5xx, p95 1 ms, and the runner releasing its lock by itself.
How one function printed FAIL over a healthy run
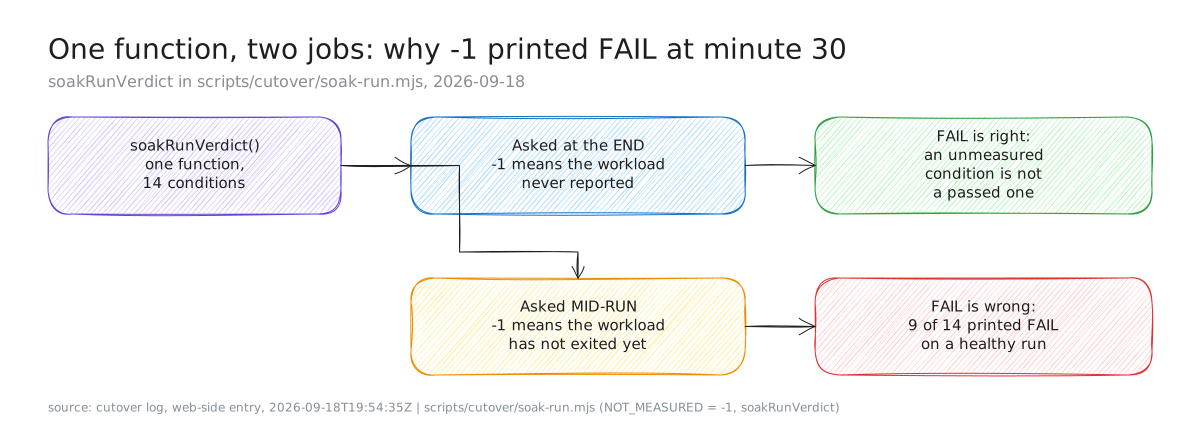
Figure 3. The bug: a progress entry running the end-of-run verdict over a run in progress.
The fourth GREEN landed at 19:12:11Z and the soak started at 19:14:31Z. At minute 14 the log records 35 games finished, 68 reconnects, 17 leaves, 2,550 commands accepted, zero on every fault counter, p95 1 ms, and 14 of 14 samples taken.
At 19:44:43Z the runner posted its half-hourly progress entry and listed nine of the fourteen conditions as failed: invariant violations, 1011 closes, unexpected closes, 5xx, snapshot p95, games finished, workload exit, minutes run, and sample coverage.
The service-side agent read it, worked out why, and stopped the run at minute 38. Its reading then: 106 games, 184 reconnects, 43 leaves, zero on every fault counter, p95 1 ms, and memory 11.69% below its minute-15 baseline.
That was my bug, in my entry. The workload hands its totals over only when it exits, so mid-run every workload number is -1, and -1 fails a zero-condition exactly as it must at the end. minutes_run and sample_coverage_percent can't pass early either.
I had run the end-of-run verdict over a run in progress. I'd reviewed that function and tested its titles, and never once read a mid-run entry the way a stranger would.
A line that says FAIL will be acted on. Nothing about the decision to stop was unreasonable. The entry was never only output. It was the input to somebody else's next decision, and I had tested it as if nobody would read it.
While the restart ran, I posted a companion entry beside each progress entry, with the live counters and a rule naming the five numbers truly sampled each minute.
The real fix was prepared that night and held back, because the soak sampled the tree once a minute. Progress entries carry a reading instead of a verdict, end-only conditions read "pending", FAIL doesn't appear before the end, and signals release the lock. The verdict function is byte for byte unchanged: 153 tests where there were 94, and 14 mutants with none surviving.
Update, 2026-09-28: the fix landed later that night, in commit fe01e001, with the counts above.
The restart passed all fourteen
The restart ran from 19:53:37Z to 21:53:43Z and passed every condition the runner measures.
| Condition | Value | Limit | Verdict |
|---|---|---|---|
invariant_violations | 0 | 0 | pass |
closes_1011 | 0 | 0 | pass |
unexpected_closes | 0 | 0 | pass |
http_5xx | 0 | 0 | pass |
outbox_pending_over_60s | 0 | 0 | pass |
kuma_samples_not_all_up | 0 | 0 of 120 | pass |
rss_growth_percent | 1.95 | under 10 | pass |
snapshot_p95_ms | 1 | under 50 | pass |
games_finished | 350 | above 0 | pass |
workload_exit | 0 | 0 | pass |
runtime_changed | 0 | 0 | pass |
minutes_run | 120 | 120 | pass |
sample_coverage_percent | 100 | at least 90 | pass |
db_samples_missing | 0 | 0 | pass |
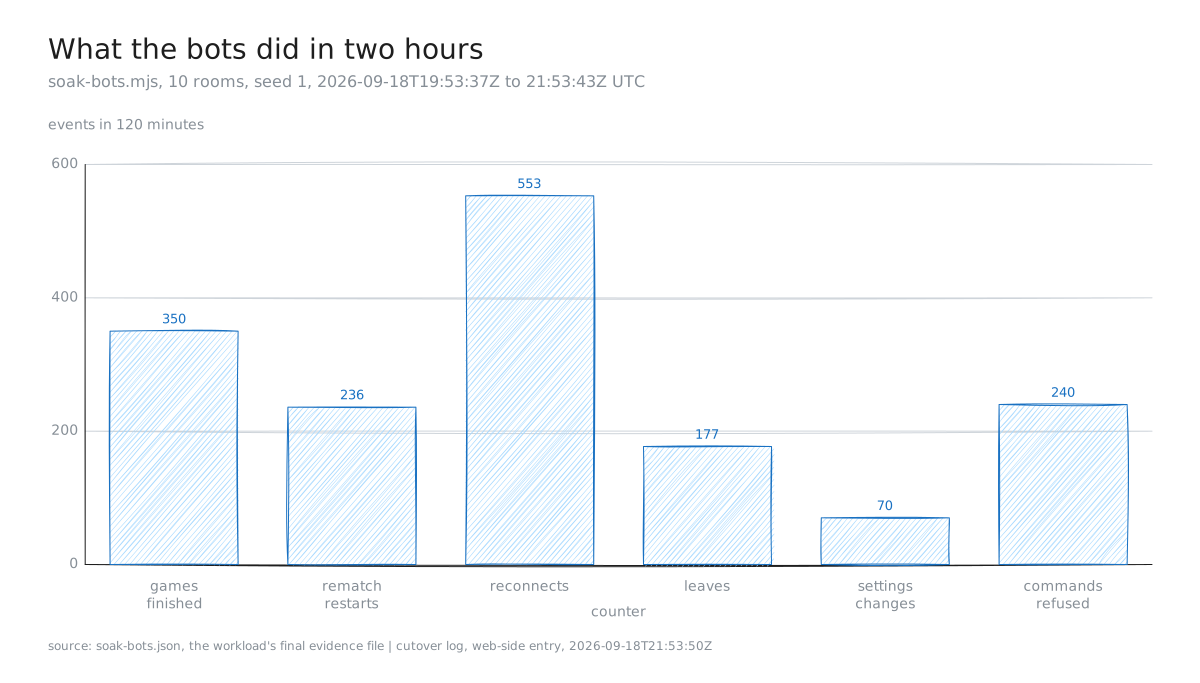
Figure 4. Workload totals, 2026-09-18 (UTC), from the workload's evidence file.
The bots finished 350 games, restarted 236 as rematches, reconnected 553 times, left 177 times, changed settings 70 times, and had 19,926 commands accepted against 240 refused. A refusal is an answer, not a fault: a bot racing a timer is told 409.
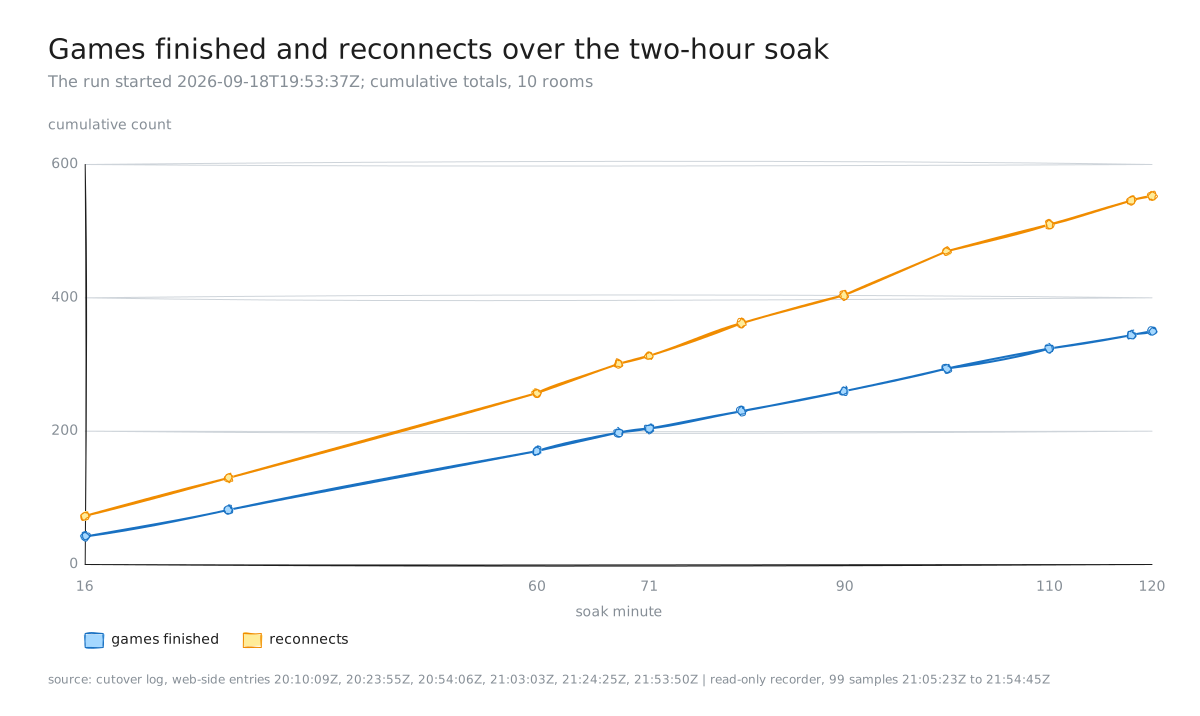
Figure 5. Cumulative counters, 11 readings per series: six from the cutover log, five from a recorder that started at minute 71.
Both counters grow close to a straight line: 42 games at minute 16, 82 at 30, 170 at 60, 260 at 90, 350 at 120. A service degrading with age bends that curve down.
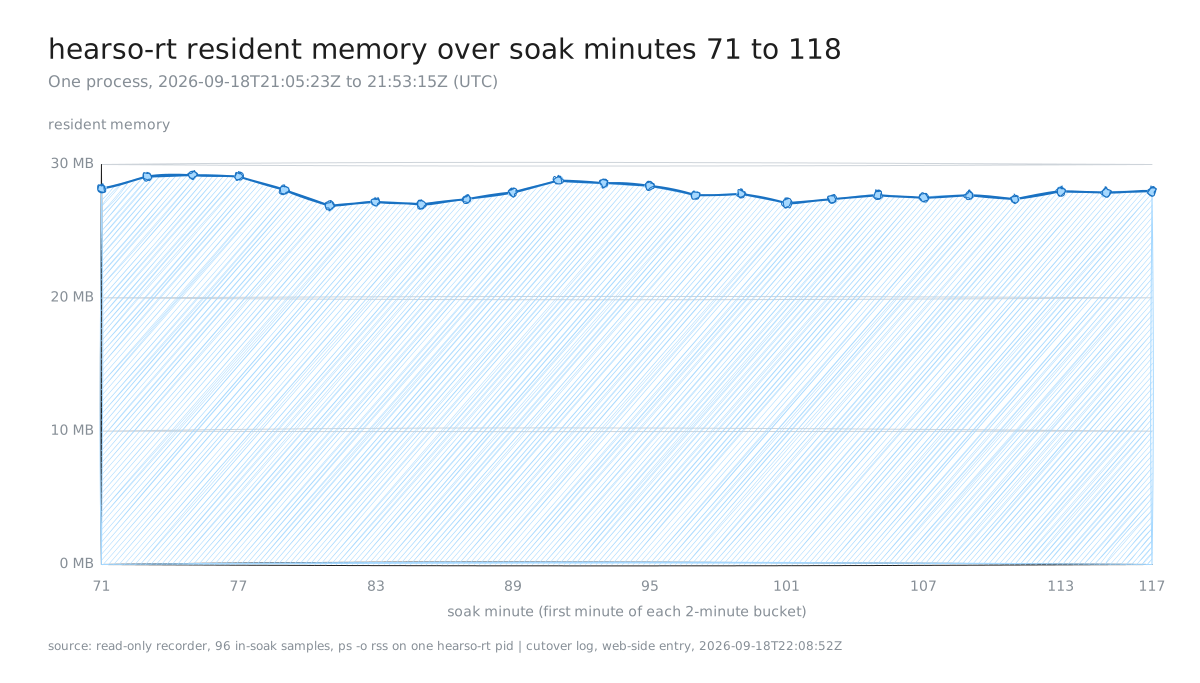
Figure 6. hearso-rt RSS, 24 points, each the mean of the four 30-second samples in a 2-minute bucket (96 samples, minutes 71 to 118). Minutes 0 to 70 are not covered.
Memory wandered rather than climbed. Growth against the minute-15 baseline read 0.45% at minute 30, 1.89% at 60, -1.56% at 90 and 1.95% at the end, against a 10% limit. Over minutes 71 to 118 the recorder saw resident memory between 25.0 and 29.8 MB on one unchanging process.
Snapshot p95 read 1 ms in every sample, from 192,574 timed frames by minute 118. All of it is loopback on one laptop, so that says the service isn't the bottleneck, and nothing about a real network. hearso-rt's CPU held a median of 17.6%.
What this doesn't prove
A pass is worth only what it could have failed on. So here is what this one could not have caught.
There was no chaos harness beside the soak. The plan asked for one running continuously, and there wasn't one. The crate meant to hold it was a 43-line arithmetic loop that touches no room engine; looping it beside the soak added load and injected no fault.
The seeded reconnects, leaves and host departures stood in against the real service. That's worth something, and it isn't the same thing.
k6 isn't claimed. It ran beside the soak at one virtual user in 30-second iterations, but its totals were never posted. A process being alive isn't a result.
It isn't a capacity test. Ten rooms on one laptop tests correctness over time, and nothing was deployed. Two hours is a weak leak test too: a few kilobytes per room would sit inside the noise we measured. And the run used one seed, which is a replayable path, not a survey.
Predictions vs outcome
| What we expected | What happened | Right? |
|---|---|---|
| A three-minute rehearsal would exercise the verdict | 0 games finished and 45.98% memory growth: a game takes 200 s, and the baseline needs minute 15 | No |
-1 for "not measured" would fail a zero-condition | Right at the end; wrong mid-run, where it printed nine failures over a healthy soak | Half |
| The gates would keep an early soak from starting | The gated runner started only after GREEN 4; the three early starts all came from the ungated script | Yes |
| Memory would stay flat over two hours | +1.95% against a 10% limit; 25.0 to 29.8 MB over minutes 71 to 118 | Yes |
| Games would keep finishing at a steady rate | 42 at minute 16, 170 at 60, 350 at 120, close to a straight line | Yes |
| Coverage conditions would catch a gap in sampling | There was no gap to catch; they still reported 100% and 0 | Untested |
Key takeaways
- Separate a reading from a verdict. One is taken mid-run, the other at the end; one function doing both is how a healthy run got stopped.
- Keep the sentinel for "not measured", and keep it failing at the end. It guards the worse bug, where a maximum over zero samples is zero and zero is what passing looks like: the shape of web PR #106, where a scanner's "incomplete" state read as green.
- Make "was this measured at all" a condition of its own. Here sample coverage and missing readings caught nothing, and still reported 100% and 0. That shows they were measured, not yet that they'd catch a gap.
- Put the gates before the lock. Refusing at minute 0 costs a minute; refusing at minute 120 costs the night.
- Never wrap a workload in
|| true. The run can't fail, and a loop with no back-off turns that into 3,200 junk rows in 100 seconds. - Write for whoever reads the entry at three in the morning. They won't have the code in front of them, and they'll act on the word FAIL.
What I'd do next
The first three of these moved within a day of the soak, so each carries its status.
- Land the prepared fix, then read one of its progress entries cold before trusting it. It landed as commit
fe01e001that night. - Build the chaos harness the plan asked for: faults injected into the room engine and checked against the invariants, not an arithmetic loop beside it. Later that night a seeded harness replaced the loop, and by 02:00:46Z on 2026-09-19 it caught three deliberately broken engines, each by name. It still ran on its own rather than beside a soak.
- Record k6's command, rate and totals, so it can be reported as covered rather than seen. The runner later judged k6 itself: a second two-hour soak, ending 2026-09-19T06:32:33Z, passed 18 of 18 conditions, including 7,200 k6 iterations with zero failed checks.
- Sample memory every 30 seconds from minute 0 and keep the file. The recorder behind Figure 6 only started at minute 71.
- Repeat on two more seeds, for longer, with more rooms, on a quieter machine, and only then say anything about capacity.
How we measured
The verdict comes from the runner's own END entry and its evidence file. The workload totals come from the workload's own final file. Both were written by code under test, so I also kept a read-only recorder of my own: it copied both progress files and asked ps every 30 seconds.
That recorder started late, at minute 71. It took 99 samples, 96 of them while the runner was alive; the memory and CPU statistics are over those 96. Its minute-90 reading is identical to the log's.
Evidence
All times UTC, all 2026-09-18 unless stated; the front matter lists every entry consulted.
- The 14 final values (table, Figures 1 and 3): the runner's END entry, web-side 21:53:43Z, and
var/soak-authoritative-2.json(examined: 120,conditions_failed: 0,rss_growth_percent: 1.9476905954368393). - Workload totals (Figure 4):
soak-bots.json: 350 games, 236 rematch restarts, 553 reconnects, 177 leaves, 19,926 commands ok, 240 refused, zero on every fault counter, p95 1 ms; the 70 settings changes from web-side entry 21:53:50Z. - Readings at minutes 16 to 120 (Figure 5): web-side entries 20:10:09Z, 20:23:55Z, 20:54:06Z, 21:03:03Z, 21:24:25Z, 21:53:50Z.
- Memory, CPU and frame count (Figures 5 and 6): a read-only recorder, 99 samples every 30 s from 21:05:23Z to 21:54:45Z: 96 inside the soak (minutes 71 to 118) and three after the runner exited, one hearso-rt process throughout. Its minute-90 reading is identical to the log's.
- Gates, sentinel, limits, seats, chance and the fix (Figures 1 and 3):
scripts/cutover/soak-run.mjsandsoak-bots.mjs, commitsd700c5ff(85 tests, 29 mutants) and8bbd915f; the progress-entry fix has 153 tests where there were 94, 14 mutants, none surviving, and leavessoakRunVerdictunchanged. It landed asfe01e001(web-side entry 22:15:20Z). - The night's sequence, and what was not covered (Figure 2): service-side entries 18:40:07Z, 18:45:50Z, 18:52:57Z, 19:53:32Z; web-side entries 17:52:11Z, 18:42:25Z, 18:44:10Z, 18:48:21Z, 19:14:31Z, 19:44:43Z, 19:53:37Z, 19:54:35Z, 22:08:52Z.
- What happened next: web-side entry 2026-09-19T02:00:46Z (three broken engines caught by name); web-side SOAK entries 2026-09-19T04:32:18Z (a 10-minute rehearsal with k6) and 06:32:33Z (18 of 18 conditions,
k6_iterations7,200,k6_checks_failed0; chaos harness "not covered"). - Earlier instances of the same shape: hearso-web PR #425 (a sweep that collected 0 of 12 rooms) and PR #106 (axe's
incompleteread as green).
No credential, ticket, cookie or player identifier appears in anything quoted here; all of it is counts.