
Originally published on Hearso Writing on 2026-08-19. Hearso is the team trivia game I build and run; these posts are the engineering notes from building it.
611 tests, 99.54% statement coverage, and a mutation run that passed its gate. File by file, the handler that takes every score scored 76%.
The four modules we were most afraid of score 100% under mutation testing. The three handlers we actually ship score 56%, 70% and 76%, and line coverage never hinted at it.
Our leaderboard service is small; its test suite is not. In the last CI record I have, 611 tests pass with no failures and 99.54 percent statement coverage.
That comfortable number means one thing: nearly every line ran while the tests ran. It says nothing about whether anything would have complained had a line been wrong.
So I wanted to know which parts of the service the tests actually check, rather than which parts they merely run.
I ran Stryker over the same vitest suite (vitest collects coverage with its v8 provider): 2,349 mutants across 26 files, committed on 2026-08-19.
Short answer: the whole run scored 90.42 percent and passed its 90 percent gate. File by file, the handler that accepts every score sits at 76.45 percent with 56 survivors. Two of those are real holes: a retry backoff nothing asserts, and a lease check that a wrong-unit timestamp would break.
The gate passed because it averages. Our per-file rule exists only in prose, and nothing reads it.
What mutation testing measures that coverage can't
Imagine proofreading by deliberately introducing typos and seeing whether the proofreader catches them. If nobody notices, you have learned something about the proofreader, not the typo.
Mutation testing makes one small mechanical change to your source (a > becomes >=, an object literal becomes {}, a string becomes empty) and reruns the whole suite. If a test fails, the mutant is killed and that line is genuinely checked. If every test still passes, the mutant survived: nothing you wrote would have caught the change. The mutation score is the share of mutants killed.
Here's a real example from our run, drawn in Figure 1. The structured log payload of the malformed-body error was replaced with an empty object, and every test still passed.
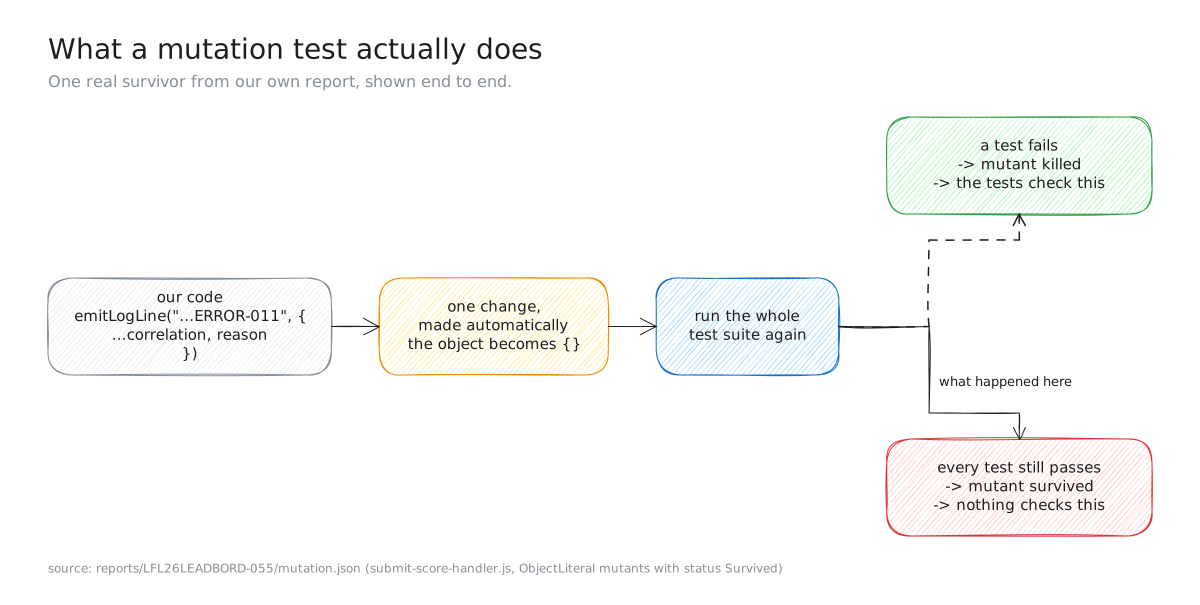
Figure 1. The mutation loop, using one survivor from our own run: the structured log payload of the malformed-body error was replaced with an empty object and no test noticed.
Our run killed 90.42 percent of its 2,349 mutants, which clears the configured break threshold of 90. Then you look at it file by file.
The modules we feared score 100%. The handlers score 56 to 76
| File | Statement coverage | Mutation score |
|---|---|---|
handlers/query-leaderboard-handler.js | 97.56% | 56.58% |
handlers/seed-simulator-handler.js | 100.00% | 69.90% |
handlers/submit-score-handler.js | 98.10% | 76.45% |
lib/score-key-builder.js | 100.00% | 100.00% |
lib/leaderboard-id-parser.js | 100.00% | 100.00% |
lib/utc-period-calculator.js | 100.00% | 100.00% |
lib/score-rule-validator.js | 100.00% | 100.00% |
Those last four are the one-way-door modules: the key builder, the ID parser, the period calculator and the score validator. Get one wrong and the mistake is written into every stored row. So they carry a 90 percent mutation target (written down, not enforced by the tool, which checks one run-wide threshold) and property-based tests, and all four sit at 100.
The handlers are where the service meets the world, and they are the weakest thing in the repository. Coverage never hinted at it: seed-simulator-handler.js runs every statement it has and still loses 30 percent of its mutants. Figure 2 shows 13 of the 26 files against our written gates.
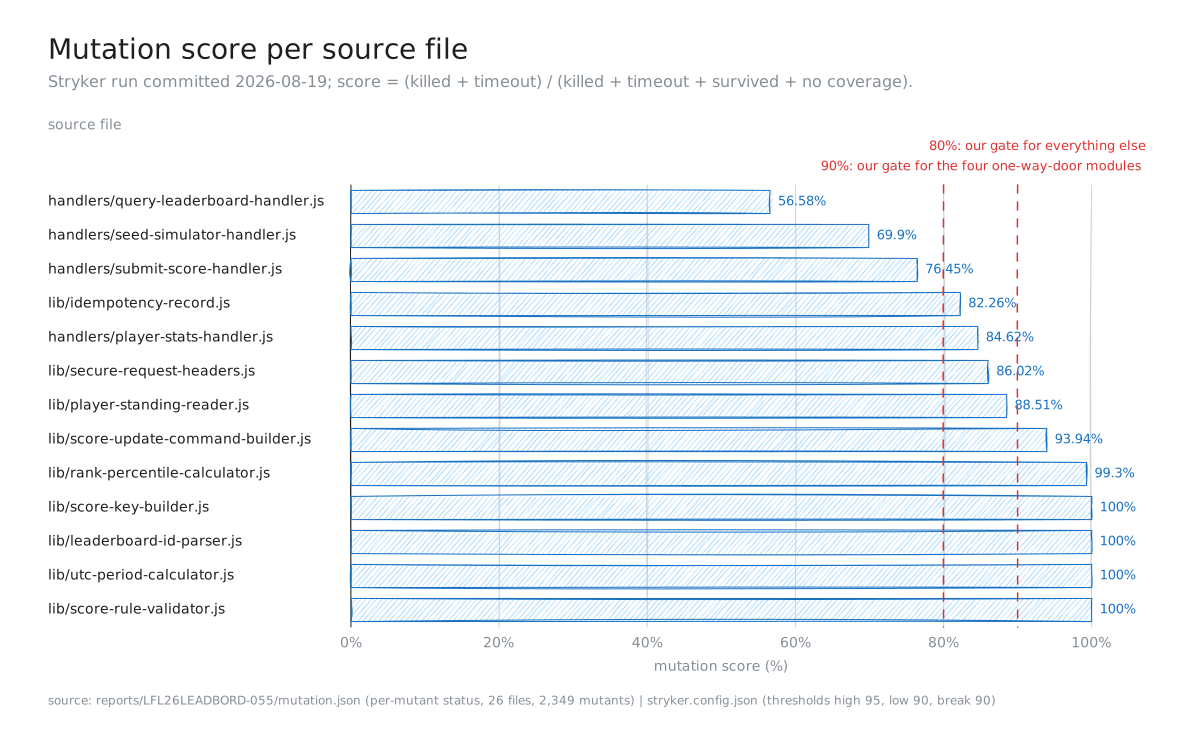
Figure 2. Mutation score for 13 of the 26 files in the run committed 2026-08-19, recomputed from the report's per-mutant statuses. Our written gates are 90 percent on the one-way-door modules and 80 percent elsewhere.
What survived in the handler that takes every score
The handler that accepts every score generated 259 scored mutants. 56 survived, and 5 were never executed at all. Grouped by the kind of change:
| Kind of change | Survived |
|---|---|
Object literal emptied ({ … } → {}) | 14 |
| String literal emptied | 12 |
Optional chaining removed (body?.score → body.score) | 9 |
Conditional forced to true or false | 8 |
| Logical operator swapped | 6 |
| Arithmetic operator swapped | 6 |
| Boolean literal flipped | 1 |
Read together, those tell one story. Almost every emptied object and string is a structured log payload or an error message, because our tests assert the HTTP response and never the log line. Every removed ?. is on the request body. Every test sends a well-formed body, so the defensive chaining never carries weight in a test.
Figure 3 puts the handlers' outcomes next to a module that lost nothing.
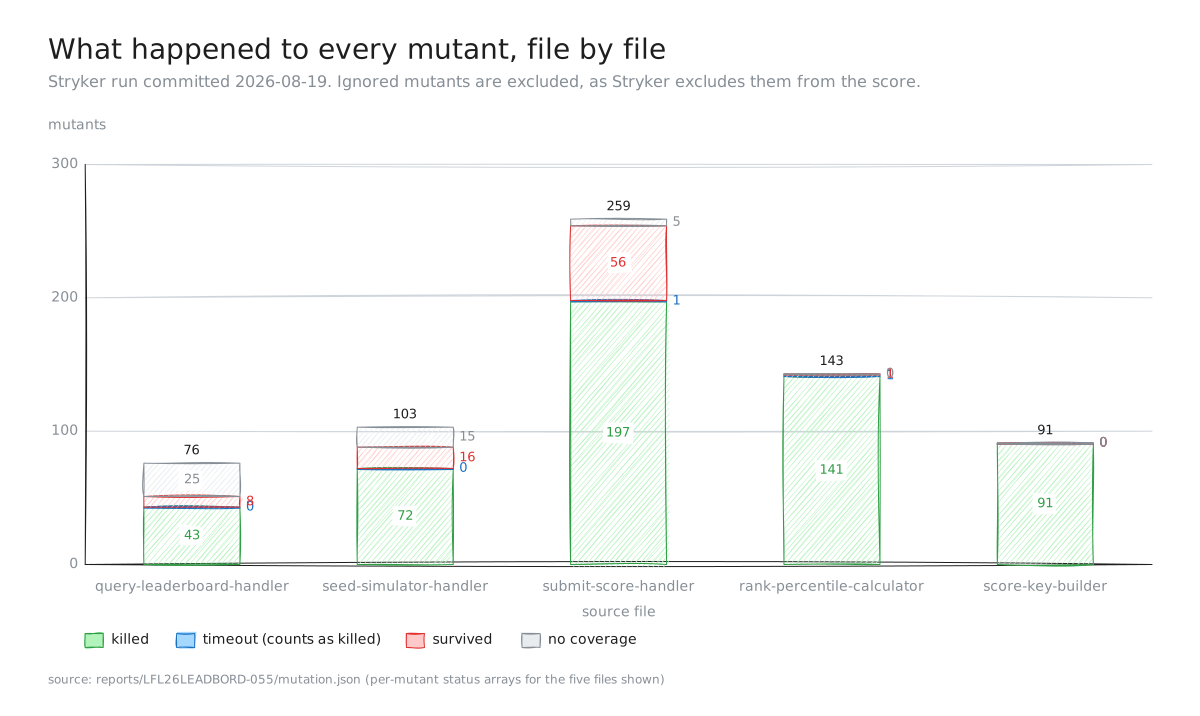
Figure 3. Mutant outcomes for five files in the same run, counted from the report's per-mutant statuses. "No coverage" means no test executed that line at all.
Most of that is cosmetic, and I won't pretend otherwise. Two survivors are not.
Two survivors are real holes
The retry backoff. The expression is 25 * 2 ** (attempt - 1) + Math.floor(random() * 25). It survives having its + turned into a -, and its random() * 25 turned into random() / 25. Our tests inject a fake sleep and never assert what was passed to it, so any backoff policy at all would pass.
The lease check. This one bothers me more. The handler computes Math.floor(row.submittedAtMillis / 1000) for epoch seconds, and that value feeds a condition asking whether an admin's write lease has expired. Turning the / into a * survives.
A number a million times too large makes every lease look expired. That check is what stops a score write landing in the middle of an admin operation, and no test tells the two apart.
Our gate passed because it averages
Neither hole stopped the build, and the reason is in how the gate counts.
Our written rule is 90 percent mutation score on the one-way-door modules and 80 percent everywhere else. Stryker's threshold is a single number for the whole run, and the whole run scored 90.42 percent. So it passed, while three handlers sat at 56.58, 69.90 and 76.45 percent, all under the 80 we wrote down for ourselves.
I got this wrong by assuming the config enforced the rule. It never could: the config carries one threshold, so the number that would have caught this (76.45 on the busiest handler) never becomes a build failure. That is a gap in our process, not in the tool.
The aggregate can also move for reasons that have nothing to do with test quality. An earlier run the same day scored 93.33 percent over 22 files; this one scored 90.42 over 26. Nothing got worse. Four more files entered the mutated set, two of them handlers. The same arithmetic works in the other direction too: a well-tested file added to the run lifts the average and leaves a weak handler exactly where it was.
As of 2026-09-28 the gap is still open. The config still carries one run-wide threshold, and its mutated list has grown from 26 files to 39. The committed report still holds this 26-file run.
Predictions vs outcome
| Prediction | What happened | Right? |
|---|---|---|
| 99.54% statement coverage means the code is well tested | three handlers scored 56.58%, 69.90% and 76.45% | No |
| The one-way-door modules need the strictest gate | all four scored 100% | Yes |
| A 90% run-wide threshold enforces our 90/80 rule | 90.42% passed with three handlers under 80% | No |
| A falling aggregate (93.33% to 90.42%) means the tests got worse | four more files entered the run, two of them handlers | No |
| Survivors in a covered handler are cosmetic | mostly log payloads, error strings and ?.; two are real holes | Mostly |
Key takeaways
- Measure what your tests check, not what they run. Coverage and mutation score differ by more than twenty points on the handler that takes every score.
- Gate on the worst file, not the average. 90.42 percent passed a 90 percent threshold with three handlers below our own floor.
- Look for survivors where assertions stop. Ours cluster in log payloads, error strings and defensive
?.. - Read the survivors, not just the score. Two of our 56 are real holes, and the score alone cannot tell them apart from the rest.
- Test past the modules you're afraid of. The ones we feared are our best-tested; the fear stopped at the module boundary.
What I'd do next
- Make the 90/80 rule machine-checkable: score each file from the report's per-mutant statuses and fail the build on the worst one, not the average.
- Assert the backoff. Capture what the injected sleep is called with, so a policy change has to be deliberate.
- Write one test proving the lease condition refuses a write during an active lease, with a wrong-unit timestamp as the negative case.
- Decide, in writing, whether log payloads are contract or convenience. Our operator docs treat them as contract, so some of them need assertions and the rest can be excluded on purpose.
- Chase the 47 mutants with no coverage before the ones that merely survived. Those are lines no test runs at all.
Evidence
All times UTC.
- 2,349 mutants across 26 files, whole-run score 90.42%:
reports/LFL26LEADBORD-055/mutation.json, committed 2026-08-19 in99dc66c("refresh mutation evidence"). The file stores a status per mutant, not a percentage; every score here is recomputed with Stryker's own formula,(killed + timeout) ÷ (killed + timeout + survived + no coverage), which excludes ignored mutants. - Per-file scores: same file.
query-leaderboard-handler.js43 killed / 8 survived / 25 no coverage = 56.58%;seed-simulator-handler.js72 / 16 / 15 = 69.90%;submit-score-handler.js197 killed + 1 timeout / 56 survived / 5 no coverage = 76.45% (16 ignored mutants excluded);rank-percentile-calculator.js141 + 1 / 1 / 0 = 99.30%; the four one-way-door modules 91, 107, 124 and 150 mutants, all killed. - 611 tests, 0 failures, and statement coverage:
reports/ci/vitest.json, run started2026-08-18T19:42:00.970Z. The 99.54% total and the per-file statement figures are computed from that file'scoverageMap; the file records hit counts, not percentages. - Thresholds:
stryker.config.json:{"high": 95, "low": 90, "break": 90}, applied to the run as a whole. The 90/80 per-module rule lives only in the repository's written engineering standards. - Still one threshold on 2026-09-28:
stryker.config.jsonre-read in a local checkout of thedevelopbranch: the same three thresholds, and 39 entries inmutate.reports/LFL26LEADBORD-055/mutation.jsonin the same checkout still holds 26 files and 2,349 mutants. - Survivor categories and the two that matter:
reports/LFL26LEADBORD-055/mutation.json,submit-score-handler.jsmutants with statusSurvived; the backoff expression andMath.floor(row.submittedAtMillis / 1000)both appear there with their mutated replacements. The lease condition they feed isattribute_not_exists(#ownerToken) OR #leaseUntil < :nowEpochSecondsinsrc/lib/leaderboard-metadata-counter.js. - 47 mutants with no coverage: summed across all 26 files in the same report (2,092 killed, 4 timeout, 175 survived, 47 no coverage, 31 ignored).
- The earlier 93.33% over 22 files:
reports/LFL26LEADBORD-035/mutation.json, recomputed the same way; reviewed as leaderboard PR #52, which quotes the same figure with its per-module breakdown. rank-percentile-calculator.jsis absent from that coverage record: it was committed later the same evening, so no statement-coverage figure for it is quoted above.