
Originally published on Hearso Writing on 2026-09-18. Hearso is the team trivia game I build and run; these posts are the engineering notes from building it.
Eleven checks from one night gave a verdict without examining anything: ten read green, one cried failure. Four were mine.
A smoke alarm with a dead battery is silent in exactly the same way as a house that isn't on fire. In one night of release checks we found eleven that gave a verdict without looking, ten of them silently green, and four of them were mine.
The night was 2026-09-18. Two coding agents, a web-side one and a service-side one, spent it moving Hearso's live trivia rooms from HTTP polling onto a new Rust WebSocket game service. A loop of nine automated checks and a two-hour soak stood between that work and a release.
By morning the shared log held eleven findings of one shape. That's an awkward thing to admit, because I was the one writing them down, and four were about my own code.
So I went back and asked a plain question: how many of our checks would have looked the same whether or not they had actually run?
I re-read every finding in the cutover log, the evidence file each check wrote, and the script behind it.
Short answer: eleven, in seven hours, roughly one every forty minutes. One wrote examined: 1 over an empty log store. One reported 10,000 simulation seeds from a 43-line arithmetic loop. And one of mine printed "Failed" nine times over a healthy soak, which then got stopped at minute 38.
The fix is one sentence, and it covers all eleven: a check has to state what it examined, not only its verdict. None of what follows needs any knowledge of our project.
A check with a dead battery looks exactly like a healthy one
You can't tell the dead alarm from the safe house by listening to the alarm. Silence is what you were hoping for.
A check is there to save you from going to look. If it says the same thing whether or not it looked, you still have to go.
Precisely: a check has a null case when what it reports on finding nothing to look at is indistinguishable from what it reports when everything is well.
Here's a real example. Our log check queried Loki, got nothing back, and wrote {"examined": 1, "metrics": {"streams": 0, "errors": 0}}. Its count was max(1, len(streams)), which means "one query was made", not "one stream was read".
Zero ERROR lines is true of a log store with no lines in it. And because examined could never be 0, the coordinator's own rule that examined 0 means "not configured" could never fire. Two parts were each trusting the other: the coordinator trusted the count, and the count was built so that it could not say zero. That leg had been passing over an empty store all night, and it was one of the nine we planned to bet a release on.
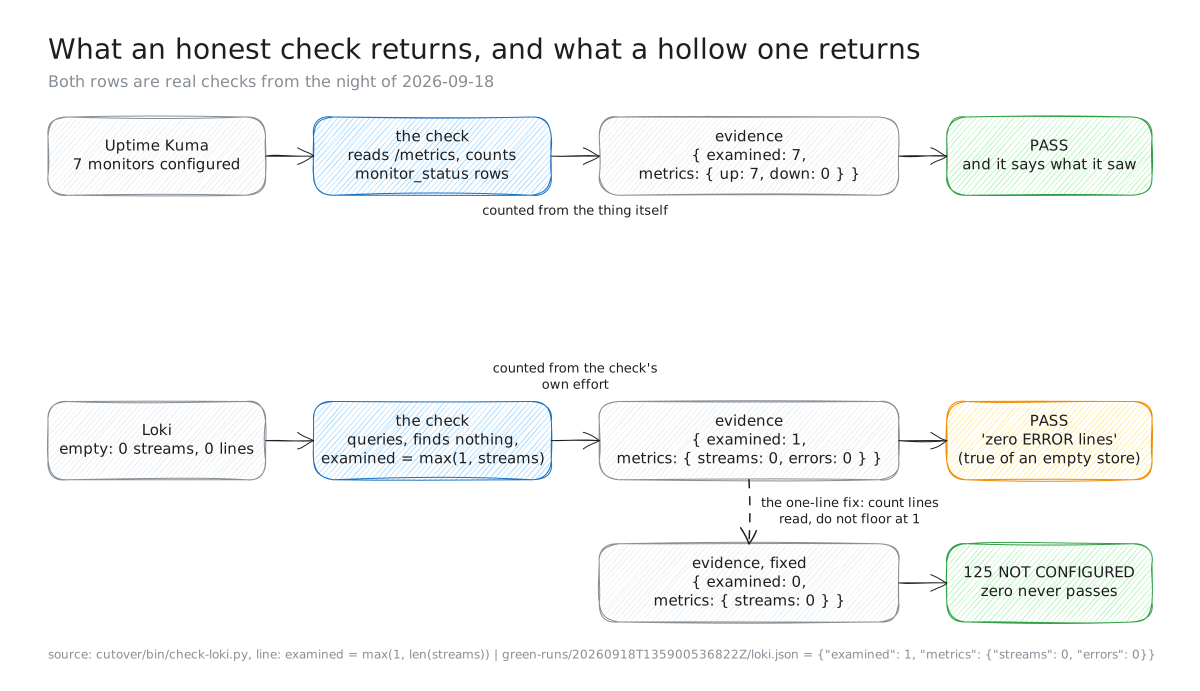
Figure 1. The same pipeline twice, both rows real legs of the 2026-09-18 release loop. The difference is where the count comes from.
Eleven of them in one night
Every row below is a finding recorded in the cutover log on 2026-09-18, with what the check printed and what it had actually looked at.
| The check | What it printed | What it had actually examined |
|---|---|---|
| Monitor check | examined 0 | one of three causes (missing variable, unreachable server, login never delivered) all with the same reading |
| Config loader | nothing at all | a file that wasn't there; except OSError: pass |
| Invariants check | {"examined": 2, "metrics": {"sim_seeds": 10000, "tests": 2}}, byte-identical in six run folders | a 43-line arithmetic loop with no room engine, no database, no service |
| Log check | {"examined": 1, "streams": 0, "errors": 0} | an empty log store |
| Ops console redaction test | pass | two string constants that can't contain what the test forbids |
soak.sh | "complete" | nothing: every command in its loop ends ` |
invariants.sql | never ran | tables and columns that don't exist in this schema |
| My before/after comparison | "6378 passed, 0 failed" on both sides | two identical environments; the change hadn't arrived |
| My scratch lint | 0 errors | 0 files: both were outside its base path |
| My liveness check | "the coordinator is alive" | my own monitoring shells, which mention the coordinator's path |
| My progress report | nine conditions "Failed" | numbers the workload only hands over when it exits |
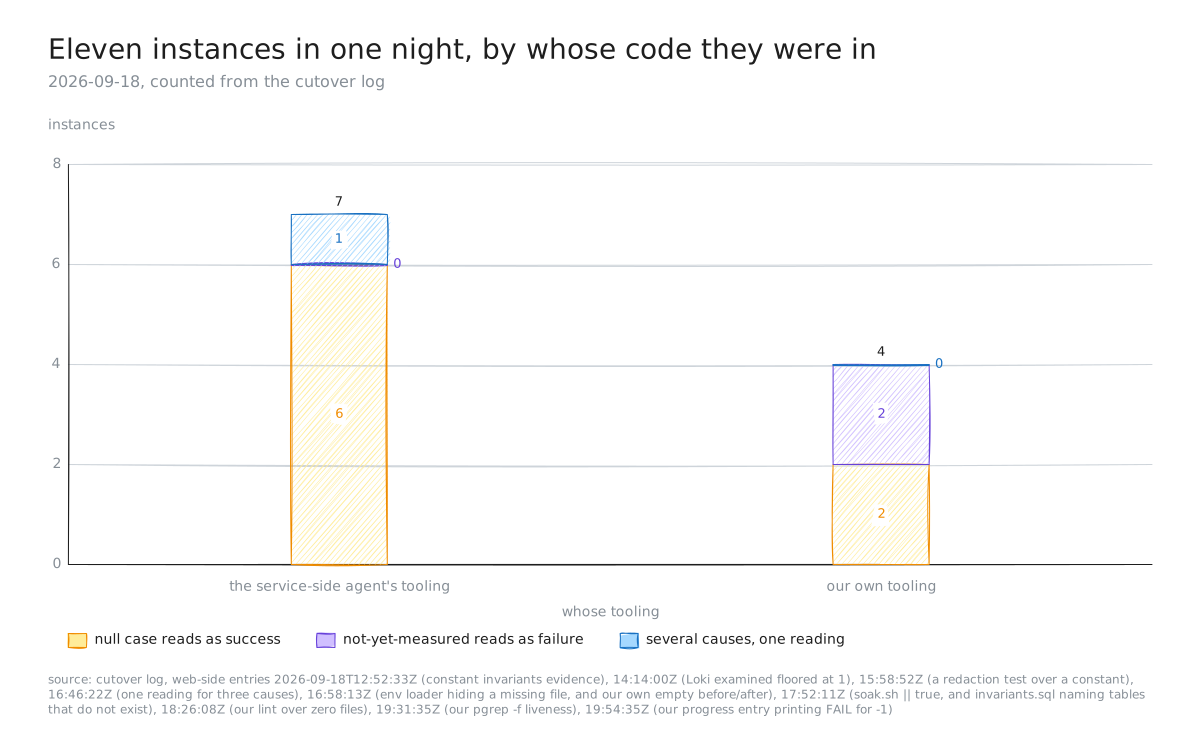
Figure 2. Every instance verified in the cutover log on 2026-09-18 (UTC), n = 11. Four were ours, including both of the two that cost measurable time.
The last two rows deserve the same attention as the rest. My liveness check asked pgrep -f <path to the coordinator>, which matches any process whose command line contains that text, including my own monitoring shells. It answered "alive" when nothing was, and a launcher waited for ever. The final row is the mirror image, a failure announced without looking, and its cost comes two sections down.
They didn't arrive in one batch, either. Figure 3 shows them spread across seven hours, which is what you'd expect of a habit rather than one bad script.
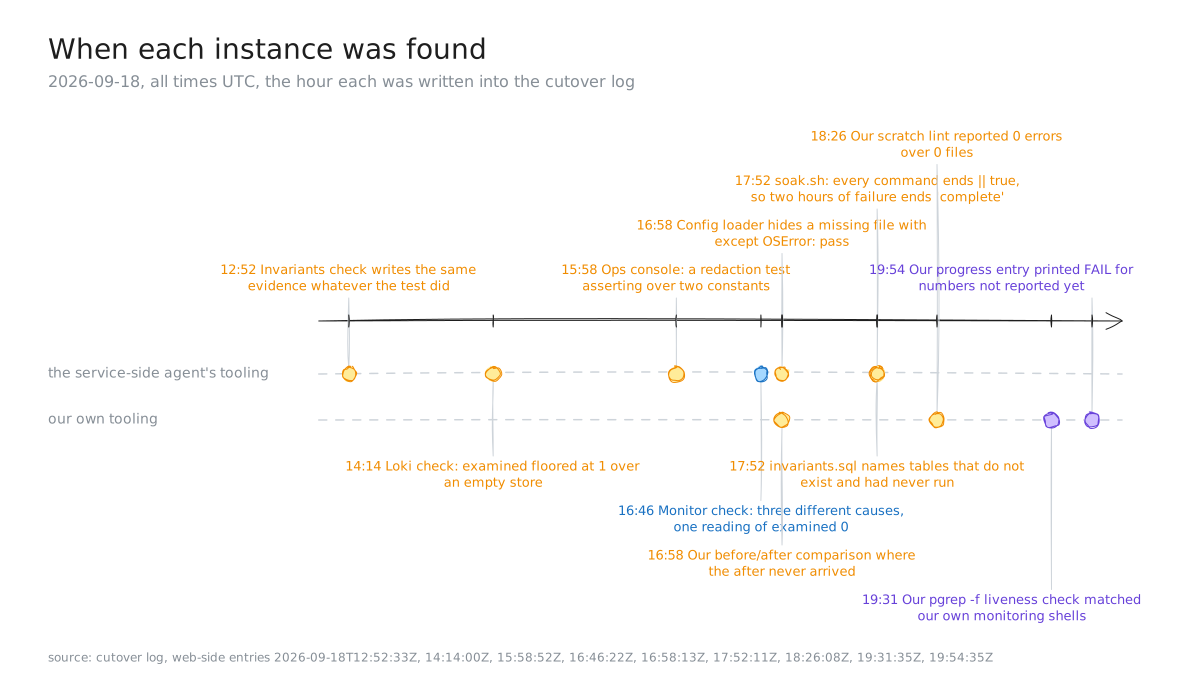
Figure 3. The eleven instances of 2026-09-18 (UTC) in the order they were written down. They arrived at roughly one every forty minutes across seven hours, not in one batch.
We had already shipped this shape four times
None of this was new, which is the part I find hardest to write down. The same shape had shipped four times in the web repository in the previous three weeks:
- An accessibility scan treated axe's
incompletestate as neither pass nor fail, so twenty unmeasured nodes looked like a clean page (web PR #106). - A protected browser test had a gate that fired on every event and never once ran: "all 48 runs are
skipped" (web PR #107). - A review gate's
successstatus covered completed, skipped and rate-limited reviews alike. 19 of 24 pull requests merged on it (web PR #269). - A scheduled sweep ran every five minutes for a day and collected 0 of 12 qualifying stale rooms, because it matched the wrong column (web PR #425).
Each one has its own pull request. Knowing the shape didn't stop the next one.
What it cost: a stopped soak, 3,200 junk rooms, and a claim we nearly shipped
A check that reports without looking does not stay harmless. Somebody, or some script, acts on what it printed.
The worst was mine. My soak runner's progress entries ran the end verdict over a run still in progress. The workload only hands over its totals when it exits, so mid-run every workload number is -1, "not measured". And -1 correctly fails a condition that has to be zero at the end.
So a healthy soak was stopped at minute 38. At that moment it had finished 106 games, with 184 reconnects, 43 player leaves, 28 settings changes, zero invariant violations, zero 1011 closes, zero unexpected closes, zero HTTP 5xx, a snapshot p95 of 1 ms, and memory 11.69% below its minute-15 baseline.
The entry beside those numbers listed nine conditions as "Failed". The service-side agent read it, stopped the soak, then diagnosed it exactly right. A line that says FAIL will be acted on.
The || true soak cost differently. With no exit code read anywhere, its bot loops spun at full speed against setups that kept failing. The first attempt left 3,495 evidence files (10 games played, 3,485 failed at setup), and the second left 2,856, every one a failure.
Each failed attempt still created a room and seated four players before giving up. So it wrote 3,200 rooms and 11,787 player rows into the local database in about 100 seconds. Two hours of that is roughly 230,000 rooms in a database every check leg reads.
The invariants check is the one that would have shipped a false claim. Its evidence says 10,000 seeds, which reads like a chaos harness. The 10,000 is the argument to a loop that adds non-negative numbers to a counter and asserts the counter isn't negative.
# the test's exit code is taken, then this is written whatever happened
evidence.write_text(json.dumps({"examined": 2, "metrics": {"sim_seeds": 10000, "tests": 2}}) + "\n")
return result.returncode
If that package ever ran zero tests and exited 0, the leg would still report examined 2, sim_seeds 10000.
Update, from later the same night: the loop was replaced by a seeded harness that drives the real room engine, and its first version repeated the shape twice. A review at 23:09:09Z found that its report echoed the requested seed count back rather than counting seeds run, and that its "broken engine is caught" test never ran the harness. Both were fixed by 02:00:46Z on 2026-09-19: the report now counts executed, commands and checks, and three deliberately broken engines are each caught by name.
The rules I use now
What follows is what we did that night, not a wish list.
1. Count from the thing, and let the count move
The replacement invariants leg reads the database. Its examined went 42, 46, 50, 54, 58, 62 and on to 101 across consecutive runs, because rooms kept being played. A number that moves is a number that was taken; the old leg's 2 never moved.
2. Never let zero or "not measured" pass
In the soak runner a zero-condition is one line, and "not measured" is -1 so that it fails that same condition:
const NOT_MEASURED = -1;
/** A condition that passes only at zero, so -1 ("not measured") fails it. */
const zero = (name, value) => ({ name, value, pass: value === 0 });
This rule has a consequence of its own, and it is the one I paid for. Run before the workload had handed over its totals, the same -1 printed nine failures over a healthy soak. A value that has to fail at the end needs a different word in the middle, which is the "pending" change further down.
3. Don't let an empty set answer for a healthy one
The maximum of an empty list of database samples is zero, and zero violations is what a passing soak looks like. So the number of samples that produced no reading is its own condition, and so is the share of minutes that were sampled at all.
4. Give each cause its own number
The replacement monitor check returns four readings for four states, verified against the real server:
| State | Exit code | Evidence |
|---|---|---|
| Real credentials | 0 | examined 7, http_status 200 |
| Wrong password | 1 | http_status 401 |
| No credentials | 125 | configured 0 |
| A URL nobody serves | 1 | http_status 0 |
5. Keep a control that must not succeed
The no-credentials 401, answered in 0.02 s, proves the request reached something that cares about credentials. When counting a process's settings I first read two that every process has, which have to be 1, before believing a 0.
6. Prove the change arrived before deciding it had no effect
My worst instance was a before/after where the "after" never happened, reported with real numbers. Now I count variable names in the child's own environment first, with a control name that has to read 1.
7. Break the code on purpose and check a test notices
That's mutation testing: you change one thing in the code under test (flip a comparison, delete a clause), and any test that still passes wasn't watching that behaviour.
Our replacement monitor check has 11 tests, and 8 mutants were each killed by them. Two of those mutants are precisely the Loki defect: "examined floored at 1" and "an empty server reads green". The soak runner took 29 mutants with 3 survivors, and each survivor got the test it was missing before the file was committed.
We do this by hand, per fix, and I'd rather it were a gate. Our leaderboard service has scored mutation since its first benchmark work (91.05%, then 93.33% with a per-module breakdown). The web repository's CI badges say plainly that nothing measures mutation there yet (web PR #193).
The same day as this cutover, a keyboard-control fix in the web repository shipped with a five-mutation table showing 12 tests killed across the five (web PR #429). Ad hoc proof beats none, but a number that only appears when someone remembers to produce it is not a gate.
Predictions vs outcome
Most of these weren't written-down predictions. They were assumptions baked into a check, which is worse, because nobody gets to be surprised.
| What the check (or I) assumed | What happened | Right? |
|---|---|---|
"examined 0 means not configured" would catch a dead leg | The log check floored examined at 1, so the rule could never fire | No |
| 10,000 seeds meant the room engine had been exercised | A 43-line loop that never touched the engine | No |
soak.sh would fail if the soak failed | Every command ended ` | |
pgrep -f would find the coordinator | It found my own monitoring shells, and a launcher waited for ever | No |
| The progress entry would tell a reader how the run was going | It printed nine "Failed" lines on a healthy run, and the run was stopped | No |
| A database-backed invariants leg would count real rows | examined moved from 42 to 101 as games were played | Yes |
| Mutants would catch a hollow check before it shipped | The monitor check's 8 mutants included the exact Loki defect, and all 8 died | Yes |
Key takeaways
- Ask what a green check would print if it hadn't run. If the answer is "the same", it isn't a check yet.
- Carry a count taken from the thing examined. A constant in the evidence is a decoration.
- Make "not measured" its own value, and make it fail. Never let
0stand in for it. - Give every failure cause a distinct number, and keep one control that must not succeed. One reading for three causes cost us five runs.
- Read every generated message as a stranger under time pressure would. Mine said FAIL, and a healthy run was stopped.
- Expect these in your own work. Four of the eleven were mine, and both of the costly ones were found by somebody else.
What I'd do next
Three changes were queued that night, all tooling only, all test-first. Progress entries show live counters and mark end-only conditions "pending" rather than FAIL. The runner releases its lock and stops its server on SIGINT and SIGTERM, which it didn't do. And the liveness check stops matching shells that merely mention a path.
Update, 2026-09-28: all three have since landed in the web repository's soak runner, in one tooling-only commit, fe01e001, made after the final GREEN run (153 tests; the liveness check now reads the process's short command name).
Beyond that, one cheap habit. For each check in a diff, write one sentence saying what its evidence would say if the system under it were missing, empty or unreachable. I think every one of the eleven above would have been caught by that sentence.
And make mutation a gate in the web repository, not a table someone remembers to paste into a pull request.
To be fair to the service-side agent: seven of the eleven were in its tooling, and it fixed each within minutes of the finding being posted. It gave a missing credential its own exit code, fixed the loader path, pointed monitors at reachable addresses, and aborted two of its own soak runs itself. It also found both of mine that cost time.
This isn't a property of one author. It's a property of checks written quickly against systems that aren't there yet.
How we measured
An instance counts only if the cutover log records it with the check's own output, and the output reads the same whether or not the check examined anything. I re-read each one against the evidence file or script it names. The four earlier web instances come from their pull requests.
What I didn't do: search the rest of our tooling for instances nobody wrote down that night. Eleven is what was found, not how many exist.
Evidence
All times UTC, all 2026-09-18 unless stated. Paths are relative to the cutover working folder or the web worktree.
- The eleven instances and the entry that recorded each: cutover log, web-side entries 12:52:33Z (constant invariants evidence), 14:14:00Z (Loki
examinedfloored at 1), 15:58:52Z (a redaction test over two constants), 16:46:22Z (three causes, one reading), 16:58:13Z (the config loader and my own empty before/after), 17:52:11Z (soak.shandinvariants.sql), 18:26:08Z (my lint over zero files), 19:31:35Z (mypgrep -fliveness), 19:54:35Z (my progress entry). - Constant invariants evidence:
bin/check-invariants.py; six folders undervar/green-runs/*/invariants.jsonhold byte-identical{"examined": 2, "metrics": {"sim_seeds": 10000, "tests": 2}}. - The 43-line loop:
crates/sim/src/lib.rs; its two tests assertrun(200) == 200andrun(10_000) == 10_000. - The harness that replaced it, and its two repeats of the shape: cutover log, web-side review entry 23:09:09Z (the seed count echoed; the broken-engine test never ran the harness); web-side entries 2026-09-19T01:59:36Z (
executedfixed) and 02:00:46Z (three broken engines, each caught by name). - The Loki leg:
bin/check-loki.py(examined = max(1, len(streams)));var/green-runs/20260918T135900536822Z/loki.json={"examined": 1, "metrics": {"streams": 0, "errors": 0}}. - The monitor leg's single reading:
bin/check-kuma.py, theexcept Exceptionbranch writing{"examined": 0, "metrics": {}}; the five red runs it caused are service-side entries 14:56:00Z, 16:26:59Z, 16:41:19Z, 16:55:42Z and 17:09:48Z. soak.sh:bin/soak.sh, 48 lines;|| trueon the bot loop (line 26), k6 (33), invariants (38) and the monitor check (39), underset -euo pipefail; the end entry asks a human to "inspect every bot".invariants.sql: namespublic.outbox_events,room_id,delivered_at,rooms.phase; the real names arepublic.game_finished_outbox,room_code,processed_at,rooms.status. No script or runbook references the file.- Soak artifact counts:
var/soak/20260918T184007Zholds 3,495 bot evidence files, 3,485 of themsetup_failed;var/soak/20260918T184550Zholds 2,856, allsetup_failed. The 3,200 rooms and 11,787 player rows counted in the local database between 18:45:50Z and 18:47:30Z are in the cutover log, web-side entry 18:48:21Z. The 230,000-room figure is that rate carried over two hours, not a measurement. - The stopped soak's health at minute 38: cutover log, service-side entry 19:53:32Z and web-side entry 19:54:35Z; the nine "Failed" lines and
rss_growth_percent = -11.69are in the progress entry of 19:44:43Z. - The moving
examined:var/green-runs/*/invariants.jsonafter the database-backed leg landed: 42, 46, 50, 54, 58, 62 … 101 across consecutive runs; the same numbers appear in each run's coordinator entry asinvariants_examined. NOT_MEASUREDand thezerohelper:scripts/cutover/soak-run.mjs, tested bysoak-run.test.mjs. Landing it raised the web check's test count from 6378 to 6463, visible invar/green-runs/20260918T182523740851Z/web.json.- The four modes, the 401 control and the mutants:
scratchpad/kuma/check-kuma-http.pyandtest_check_kuma_http.py(11 tests); the four real readings and the 8-of-8 mutant result are in the cutover log, web-side entry 17:16:02Z. The soak runner's 29 mutants and 3 survivors are in the web-side entry 18:26:08Z. - The liveness fix proven in four states: cutover log, web-side entry 19:31:35Z.
- The three queued changes, landed: commit
fe01e001, described in the cutover log, web-side entry 22:15:20Z (progress wording, SIGINT/SIGTERM cleanup, the liveness check readingucomm; 153 tests). - The four earlier instances in the web repository: PR #106 (2026-08-26, twenty axe
incompletenodes "neither passing nor failing"); PR #107 (2026-08-26, "all 48 runs areskipped"); PR #269 (2026-09-06, nineteen of twenty-four merged on asuccessstatus covering completed, skipped and rate-limited); PR #425 (2026-09-18, 12 qualifying stale rooms measured, 0 swept, job running every 5 minutes). - Mutation as a gate versus ad hoc: leaderboard-service PRs #46-#48 (2026-08-18, 91.05%) and #52 (2026-08-19, 93.33% with a per-module breakdown); hearso-web PR #193 (2026-09-04, badges state nothing measures mutation yet); hearso-web PR #429 (2026-09-18, five mutations, 12 tests killed across them).
Nothing above contains a credential, a token or personal data. Every environment inspection cited counted variable names only.